“I don’t see her”
Picture a robot covering one eye with a metal hand. With the other hand, he points directly at the elegant robot standing behind him and insists:
I don’t see her.
It sounds convincing until you ask the obvious question: if he is not paying attention to her, how does he know exactly where she is?
That is roughly what happens when we tell an AI system:
Do not sound promotional. Do not use clichés. Do not mention the competitor. Do not think about her.
The instruction appears strict, but it has also placed promotion, clichés, the competitor, and her directly inside the model’s working context. The model may not intend to disobey. It simply has to process the concepts we just made relevant.
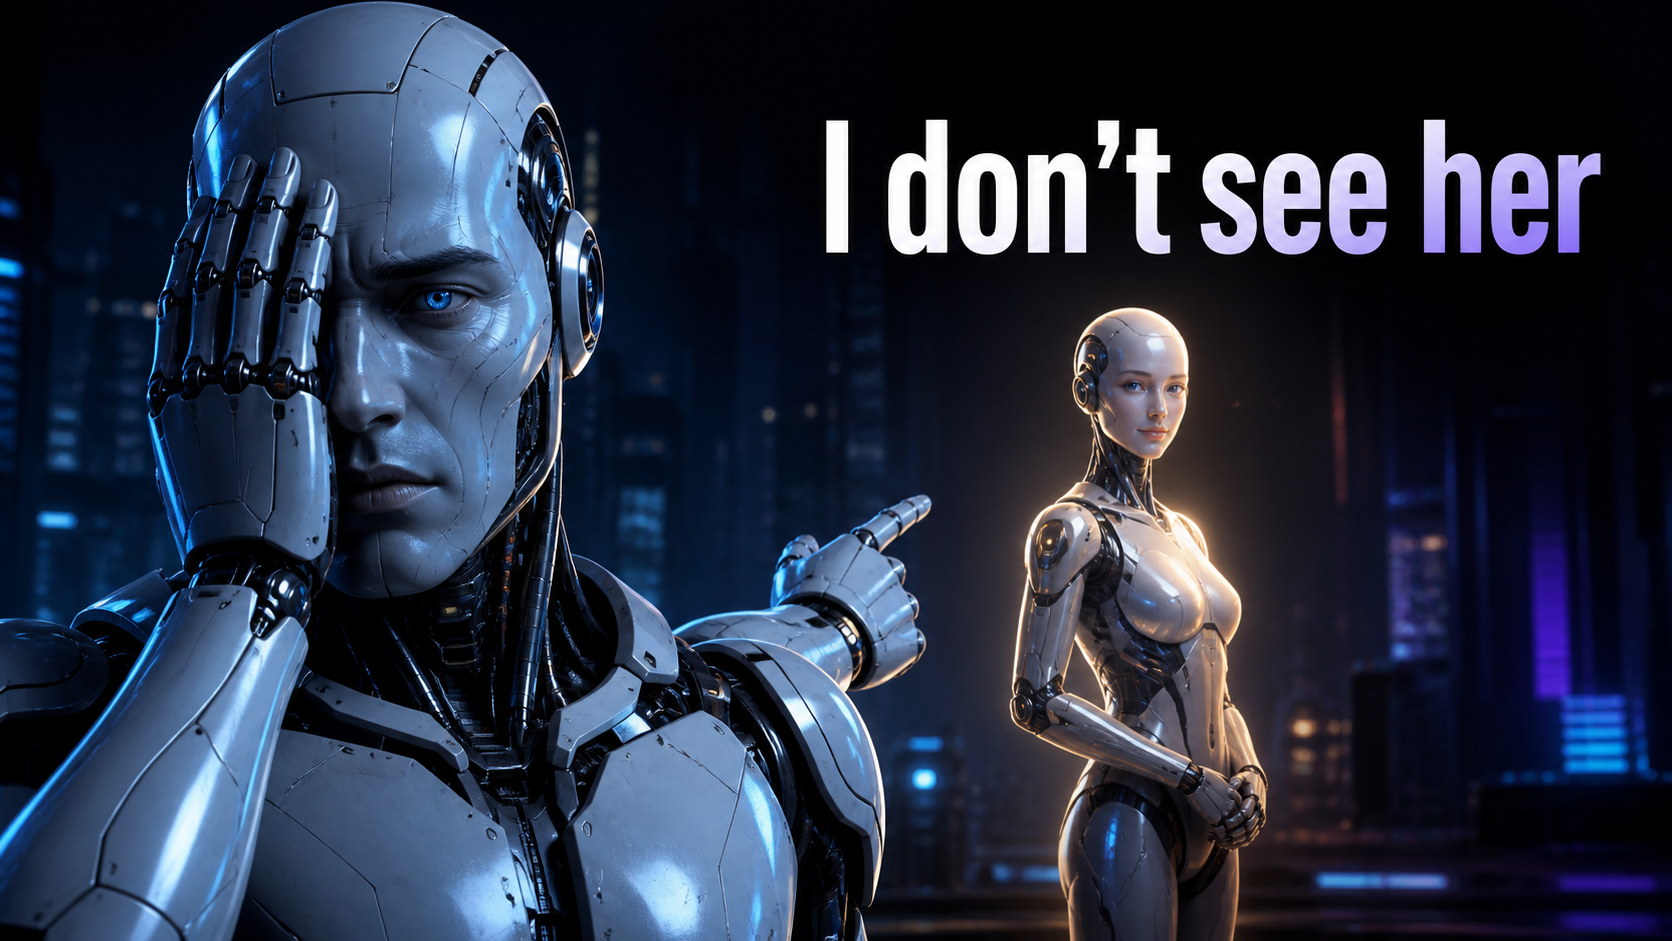 The prompt says not to look, while directing all attention toward the forbidden subject.
Is AI actually curious?
Not in the human sense. A language model does not feel attraction, jealousy, embarrassment, or the urge to discover something hidden. There is no forbidden lover waiting in its subconscious.
But language models are trained on language produced by humans. That language contains our associations, narrative habits, metaphors, and ways of connecting one idea to another. Once a concept appears in the prompt, it becomes part of the context used to predict what comes next.
If we call this “AI curiosity,” the careful term would be statistical curiosity. The model does not want to look at her. The probability of its next words has simply been pulled in her direction.
The white bear problem
In 1987, Daniel Wegner and his colleagues ran a famous experiment in which participants were asked not to think of a white bear. Monitoring whether they had succeeded required them to keep checking for the bear. The study found that attempted suppression could make the thought rebound afterward. Paradoxical Effects of Thought Suppression
An LLM is not a human mind, so this experiment does not prove that AI has an unconscious. The analogy is useful for a narrower reason: a forbidden idea must first be represented before it can be excluded.
For a language model, “not” is not a delete key. It is another token whose scope has to be composed with the correct concept while generation continues.
Research on negated prompts shows that this is a real weakness. One study converted nine familiar tasks into negated versions and found that larger models did not automatically improve; in some settings, performance became worse as models scaled. Can Large Language Models Truly Understand Prompts?
Another benchmark of roughly 400,000 commonsense statements found that models handled negative statements less reliably than affirmative ones. This is not a Dataset
This does not mean models cannot understand negation. It means prohibition is not always the most reliable control surface.
Describe the road, not only the ditch
Suppose you want a concise management report. A common prompt says:
Do not be verbose. Do not be vague. Do not sound promotional.
That describes failure in detail but leaves success mostly undefined. A more useful prompt says:
Write for a busy manager. Give each paragraph one concrete claim, one example or data point, and one implication for the decision. Keep the response below 800 words.
Now the model knows the audience, the structure, and the stopping point.
Anthropic’s prompting guidance follows the same principle: be explicit about what the model should do, provide context, and use a prompt style that resembles the desired output. Prompting best practices
Every prohibition creates another thing to remember
A long denylist gives the model three jobs at once:
- remember what is forbidden;
- determine where each prohibition applies;
- invent an acceptable replacement.
As the prompt grows, constraints compete with content, tone, length, format, and one another.
The DeCRIM study reported that even GPT-4 missed at least one constraint on more than 21 percent of multi-constraint instructions in RealInstruct. Its more effective approach was to decompose the constraints, inspect failures separately, and repair the specific defect. LLM Self-Correction with DeCRIM
When a prohibition is necessary, give the model an exit path.
| Instead of only saying | Specify this behavior |
|---|---|
| “Do not speculate.” | “Use only the supplied evidence. If it is insufficient, state what information is missing.” |
| “Do not be verbose.” | “Write three paragraphs of no more than three sentences each. Begin with the conclusion.” |
| “Do not sound like AI.” | “Write like a practitioner explaining the issue candidly to a colleague.” |
| “Do not mention competitors.” | “Limit the comparison to customer needs and verified product evidence.” |
Some rules should never be entrusted to prose
It is tempting to conclude that better prompting solves the entire problem. It does not.
If an AI can transfer money, delete files, read private data, or call a production system, “do not make a mistake” is not a control. The system needs enforcement outside the prompt.
Practical examples:
- If JSON must match a structure, validate it with JSON Schema.
- If the model must not delete files, do not grant delete permission.
- If only three tools are allowed, expose only those three tools.
- If sensitive data must not reach the model, filter it before inference.
The model may propose an action. Software decides whether that action can happen.
Soft guidance through language, hard limits through architecture
Not every constraint needs the same enforcement mechanism.
Language is well suited to guiding tone, intent, and presentation. Architecture is better at controlling permissions, data structures, and actions with a large blast radius.
The rule is simple: if something must never happen, do not merely ask the model to remember the prohibition. Design the system so the action is impossible.
Before adding another “don’t”
Ask five questions:
- What does success look like if I never mention the failure?
- Have I defined the audience, purpose, and output shape?
- Can I provide a short example of the desired result?
- Does this boundary include a replacement behavior?
- If this is a hard limit, why is it not enforced by software?
Conclusion
The robot covering his eye while pointing directly at her is a useful joke. The AI does not love her, and it is not curious in the way we are.
But language models are built from human language, and language leaves traces. The moment we say “do not think about her,” we have placed her at the center of the prompt.
If you want a better output, describe the destination clearly. If you need to prevent a dangerous action, enforce the boundary in software. And if you stand at the trailhead shouting “never enter the forest,” do not be surprised when the entire conversation becomes about the forest.